
AI engines decide who to recommend through three doors: Reach, Recognize and Believe. I audited more than 100 websites in seven countries through September 2026. Nearly nine in ten had closed at least one door, and most of the fixes cost nothing.
Popular Posts
Latest Articles

The Three Doors of AI Visibility: A Study of 100+ Websites
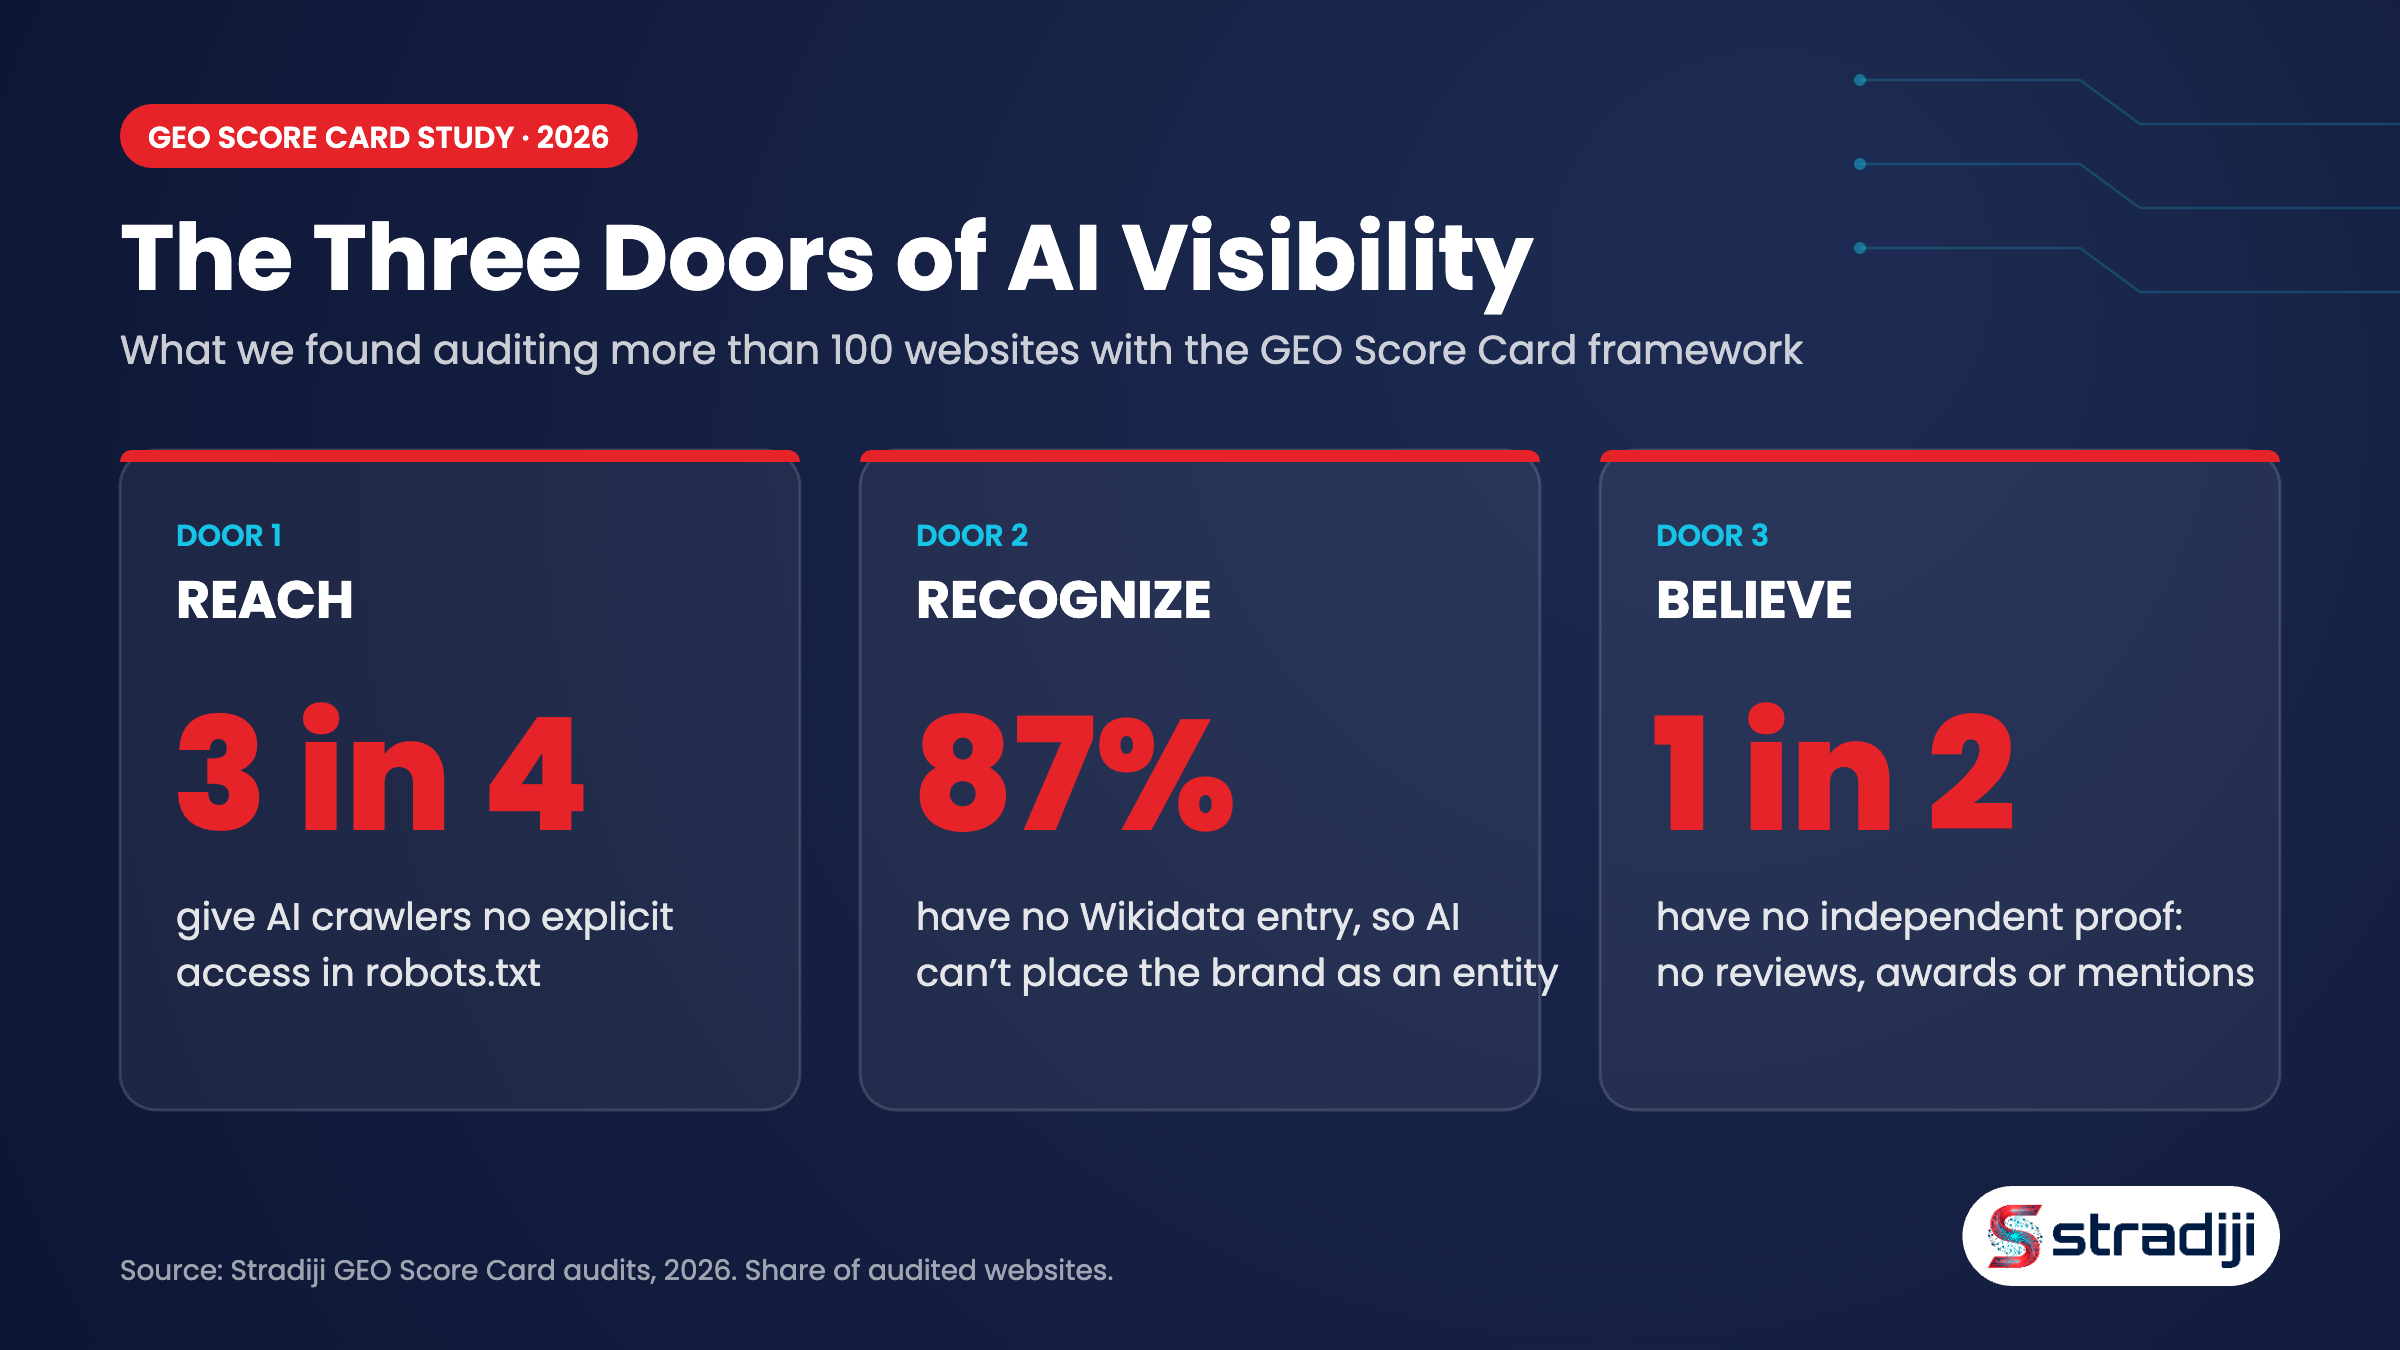
First, reach: can the engine get into your site? Second, recognize: does it know you as an entity? Third, believe: does it trust what it says about you? Each door depends on the one before it. A brand the engine can’t reach can’t be recognized, and a brand it doesn’t recognize can’t be believed.
Let me be clear: this does not mean your content is bad. Content and technical SEO were relatively fine on most sites I audited. The problem is whether these three doors are open. The good news: the list is short and the same for everyone. The first to open the doors pulls ahead.
Key findings at a glance
| Door | The question | What we found | Fastest fix |
|---|---|---|---|
| 1. Reach | Can AI engines get in? | About 3 in 4 sites give AI crawlers no explicit access in robots.txt. Some block GPTBot, ClaudeBot or PerplexityBot outright. | Open robots.txt and your CDN bot settings. About five minutes. |
| 2. Recognize | Does the engine know you as an entity? | About 87% have no Wikidata entry, about 3 in 4 have no Wikipedia article and about 30% lack basic Organization schema. | A free Wikidata item, linked from your Organization schema. |
| 3. Believe | Does the engine trust what it says about you? | About half have no independent reputation signal. About two thirds lack a citation-ready Q&A structure. | Earn and document one independent proof point. |
| Overall | Is at least one door closed? | Nearly 9 in 10 sites. | Start with Reach. Nothing else holds until engines can get in. |
Study details (transparency matters)
Scope: Through the GEO Score Card program I audited more than 100 websites in depth through September 2026, as part of client and prospect engagements. That makes this a practitioner sample, not a random one. Read the rates as a photo of the set I audited, not of the whole web.
Where: Turkey, the U.S., the U.K., Germany, Estonia, Romania and South Korea. Sectors: health and medical tourism, e-commerce, B2B software, real estate, local services, media, law, manufacturing and travel.
Method: I crawled each site in full with Screaming Frog, reviewed robots.txt, llms.txt, ai.txt and AGENTS.md in Chrome, read the Agentic Browsing section of PageSpeed Insights, pulled market data from Semrush, and ran live tests in ChatGPT, Perplexity, Gemini and Google’s AI features. Every figure in the study is a share of all audited sites, weighted equally.
How the numbers fit together: “Nearly nine in ten closed at least one door” is a floor, not a model. If about 87% of sites have no Wikidata entry, at least that many have the Recognize door partly shut, before we count Reach or Believe.
70 checks, then 38: The audits ran on the 70-check version of the GEO Score Card. In October 2026 I condensed the public self-check into 38 checks across the same three doors, plus a short Measure section. I dropped checks that didn’t change decisions, such as ai.txt and AGENTS.md, and added the ones the data said mattered most.
What this study does not claim: An open door is a precondition, not a guarantee. An open robots.txt file does not mean an AI engine will cite you. AI answers are personalized and the default models change every few weeks, so we report shares and citations, never “AI rankings.”
Door 1: Reach. Can the engine get in?
The most basic door, and the most surprising. About three quarters of the sites I audited give AI crawlers no explicit access in robots.txt. A subset does something worse: it blocks GPTBot, ClaudeBot and PerplexityBot outright.
Then the same brand asks why AI never recommends it. It is like locking the door, peering through the window and asking why nobody comes in. Most of this isn’t deliberate. It’s an old security or bandwidth rule nobody revisited.
Not every AI bot does the same job
This is where most sites go wrong. They block “AI bots” with one rule and cut off AI search along with AI training. Each company runs separate crawlers for separate jobs, and each one is a separate decision.
| Company | Search (gets you into answers) | User-triggered (fetches a page when someone asks) | Training (feeds future models) |
|---|---|---|---|
| OpenAI | OAI-SearchBot | ChatGPT-User | GPTBot |
| Anthropic | Claude-SearchBot | Claude-User | ClaudeBot |
| Perplexity | PerplexityBot | Perplexity-User | (not a separate bot) |
| Googlebot (also feeds AI Overviews and AI Mode) | n/a | Google-Extended (a control token for Gemini training and grounding, not a crawler) | |
| Apple | Applebot | n/a | Applebot-Extended (control token) |
Two rules follow. First, keep the search and user-triggered bots open if you want to appear in AI answers. Second, treat training as a licensing decision, not a technical one. You can block GPTBot and still be cited in ChatGPT search, because OAI-SearchBot does that job. Blocking Google-Extended does not remove you from AI Overviews; Googlebot governs that.
Here is what an intentional robots.txt section looks like:
# AI search and user-triggered fetches: allowed
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Perplexity-User
Allow: /

# AI training: your licensing decision
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: Applebot-Extended
Allow: /
# Change to "Disallow: /" if you choose to opt out of training
The firewall trap: robots.txt says yes, the CDN says no
Your robots.txt is a request. Your CDN or firewall is the actual door. On Sept. 15, 2026, Cloudflare changed its defaults: for new domains, Training and Agent bots are blocked on pages that display ads, while Search stays allowed. The bigger catch is mixed-purpose crawlers. Googlebot, Bingbot and Applebot do search and training in one crawler, so any Cloudflare setting that blocks Training, including the old “Block AI bots” toggle, now blocks them too.
That means a site owner can restrict both search and AI crawlers without ever meaning to. Search Console can look healthy while the block sits at the network layer, where most SEO tools never look.
What to check: In Cloudflare, open Security Settings, then the AI bot policies. Set Search, Agent and Training on purpose, one by one. If you run another CDN or a WAF, ask your developer for the bot rule list and look for GPTBot, OAI-SearchBot, ClaudeBot, Claude-SearchBot and PerplexityBot.
Getting in is not the same as being read
Once a bot is in, it reads very little. In ChatGPT’s case, the engine keeps roughly the title, the URL and about 200 characters from the top of the page body. Not your meta description. A date, a breadcrumb or a long image alt text above your first sentence eats that budget. Three habits help:
- One H1 per page, with the answer in the first sentence below it.
- The core answer in plain HTML. Most AI crawlers do not run JavaScript.
- No
nosnippetor tightmax-snippeton pages you want quoted.
A correction on Bing
The first version of this study said ChatGPT grounds heavily on Bing’s index. That is no longer the right reading. In September 2026, evidence showed ChatGPT runs its own family of search indexes plus several outside providers, with Bing showing up mostly in Deep Research. Being indexed in Bing still matters for Copilot and as a backup, but it’s no longer a proxy for ChatGPT visibility. Measure ChatGPT as its own engine.
And llms.txt?
On most sites I audited, llms.txt was missing or broken. Be honest about it, though: llms.txt is not a Google ranking factor, and real AI-bot use of it is very low today. Treat it as a low-cost, low-risk extra for some non-Google engines. The door is opened by robots.txt and your CDN settings.
Score this door: The Reach section of the GEO Score Card has 12 checks, from bot access and CDN rules to the first 200 characters and ChatGPT’s cache.
Door 2: Recognize. Does the engine know you as an entity?
Reaching you is not enough. The engine must recognize you as an entity: one specific company, in the right category, next to the right competitors. Here is the biggest shared gap: roughly 87% of the sites I audited have no Wikidata entry.
Wikidata is an open entity database that feeds Google’s Knowledge Graph and many AI systems. If your brand isn’t there, the engine either never mentions you or confuses you with another entity. The other locks on this door are shut too: about three quarters have no Wikipedia article, and roughly 30% lack even a basic Organization schema.
What confusion looks like, from my own brand
In August 2026 I asked Gemini about Stradiji with web search turned off. It didn’t know us. Worse, it read “Stradiji” as a misspelling of Stradivarius and declined to answer. With search turned on, it found us and got the founding year right. That is the lesson: confusion usually lives in the model’s memory, not in search, so test both ways.
The 10-minute category test
Ask two engines, logged out, in a new chat:
- “What is [brand]?” Does the answer match your category?
- “What does [brand] do?” Is the description current?
- “Who are [brand]’s competitors?” This is the most revealing one. The competitor list is the mirror of the category the model filed you in. Wrong list, wrong positioning, and no amount of new content fixes that.
How to create a Wikidata item, step by step
A Wikidata item is free. Search first to make sure your brand doesn’t already have one. Then create the item with a clear label, a plain description (“[category] company based in [city]”) and aliases for every spelling people use. Add these statements, each with a reference to a public source:
| Property | What it says |
|---|---|
| P31 instance of | business, or the most specific type that fits |
| P452 industry | your category |
| P17 country / P159 headquarters location | where you are |
| P571 inception | founding year, exactly as on your About page |
| P112 founded by | the founder, if public |
| P856 official website | your homepage URL |
| P4264 LinkedIn company ID, P2002 X username, P2397 YouTube channel ID | your official profiles |
Two cautions. Wikidata has its own notability policy: the item needs serious, publicly available references. And if you’re editing your own company’s item, disclose the conflict of interest and stick to referenced facts. No adjectives, no marketing copy.
Then tie it together with schema
Link the Wikidata item from your site’s Organization schema sameAs array. That tells engines: this site, this Wikidata item and these profiles are one entity, not scattered fragments.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "@id": "https://www.example.com/#organization",
  "name": "Example Co.",
  "alternateName": "Example",
  "url": "https://www.example.com/",
  "logo": "https://www.example.com/logo.png",
  "description": "Example Co. is a [category] company for [audience].",
  "foundingDate": "2015",
  "founder": { "@type": "Person", "name": "Jane Doe" },
  "sameAs": [
    "https://www.wikidata.org/wiki/Q00000000",
    "https://www.linkedin.com/company/example",
    "https://www.youtube.com/@example"
  ]
}
Keep the founding year, name and category identical on the site, in schema, on Wikidata and on every profile. Small variations split one brand into several weak entities.
Score this door: The Recognize section of the GEO Score Card has 12 checks, including the competitor test, the memory test with search turned off and hallucination tracing.
Door 3: Believe. Does the engine trust what it says?
Say the engine reached you and recognized you. One more door: does it believe what it says? AI is no longer a signpost; it’s a narrator. Users form a judgment from the sentence the engine writes, often without clicking. If there’s no proof behind that sentence, both the user and the engine treat it as an empty claim.
In my data this door is half shut: half the sites have no independent reputation signal. No third-party review, no award, no industry mention. About two thirds also lack a citation-ready Q&A structure.
Your site corroborates. Other people’s pages get you named.
An engine checks your own site to verify a claim. It looks at third-party pages to decide whether to name you. Your resume saying “great team player” matters less than a reference letter from your last boss. That’s why the gap between known brands and merely findable ones is so wide: in an August 2026 analysis of ChatGPT network traffic by Suganthan Mohanadasan, brands the model wrote into its own search queries from memory were named in 68.9% of answers, versus 2.1% for brands it only found through search. I wrote that up in ChatGPT Decides Before It Searches.
What counts as independent proof
- Reviews on a platform you don’t control: G2, Capterra, Trustpilot, Clutch or your industry’s equivalent.
- An award or ranking with a public winners list.
- Earned media: a journalist or industry publication writing about you on its own initiative.
- A customer publishing a case study about working with you.
- Inclusion in independent comparisons and “best of” lists that engines already cite for your category.
- Original data that other sites quote.
An honest note on this study’s own distribution: we released it as a press release on Oct. 12, 2026. Syndicated press releases are useful for reach, but they’re self-published. They don’t count as independent proof. What counts is someone else writing about the data.
Proof beats posture
The page that gets cited isn’t the one saying “we are the leader.” It’s the one documenting “we were included in this independent list, we won this award, we produced this data.” In July 2026, when I tested Google’s AI answer for “best credit card” in Turkey, the only bank page cited was one that documented its card’s inclusion in an independent international ranking. Replace your “we’re the best” lines with independent proof. What the engine trusts is not an adjective; it’s a document.
Structure helps too. A short Q&A block on key pages, written the way buyers actually ask, gives engines a clean passage to quote.
Score this door: The Believe section of the GEO Score Card has 10 checks, from review profiles to earned media in the last 12 months.
A fourth habit: measure the same way every month
Doors open and close. A firewall update, a plugin change or a new default model can undo last month’s work. Keep a small monthly panel: the same buyer prompts, at least four engines, logged out, with the model and date written down. One run is a lead, not a finding. Add two free first-party sources: Search Console’s generative AI performance report (open to all sites since Aug. 31, 2026, impressions only) and AI referrals in GA4 (chatgpt.com, perplexity.ai, gemini.google.com). The Measure section of the Score Card lists all four checks.
Counter-thesis: “so many gaps means this is hard”
Don’t read the long gap list as “GEO is complex.” It’s the opposite. The gaps being this shared is the most hopeful part, because the same short list keeps repeating: bot access, a Wikidata entry, basic schema, one independent reputation signal. This is not rocket science. If the industry average is this low, the reason isn’t difficulty. These known items were simply never addressed. We are early, not late.
Is this a local problem? No, it’s a maturity problem
The first thing I wanted to know: are Turkish sites behind, or is this global? The data was blunt. Foreign sites have the same gaps. An Estonian software firm with no Wikidata, a German travel site with a broken llms.txt, a few U.S. sites with no schema at all. “We’re not ready for AI” isn’t a regional excuse. It’s a maturity stage, and the competition hasn’t solved it either. The first to do it well pulls ahead.
Open the doors this week: a 30-minute check
| # | Door | Do this | Time | Tool |
|---|---|---|---|---|
| 1 | Reach | Open yoursite.com/robots.txt. Remove any Disallow for OAI-SearchBot, ChatGPT-User, Claude-SearchBot, PerplexityBot. Decide training bots on purpose. | 5 min | Browser |
| 2 | Reach | Check your CDN or firewall AI bot settings, especially Cloudflare’s Training setting. | 5 min | Cloudflare dashboard |
| 3 | Recognize | Search your brand on Wikidata. No item? That’s the week’s highest-return task. | 2 min | wikidata.org |
| 4 | Recognize | Run your homepage through the Rich Results Test. Is there an Organization schema with sameAs? | 3 min | Rich Results Test |
| 5 | Recognize | Ask two engines “Who are [brand]’s competitors?” Is the list right? | 5 min | ChatGPT, Gemini |
| 6 | Believe | Ask “What is [brand], is it trustworthy?” Is there proof behind the answer, and whose pages are cited? | 5 min | Perplexity, AI Mode |
| 7 | All | Score yourself on the 38 checks and get your weakest door by email. | 10 min | GEO Score Card |
How long until AI answers change?
Not tomorrow. Engines usually answer from copies of your pages they crawled earlier, not from a live fetch. A fix has to be recrawled before it reaches the answer. Prompts where the engine searches the web can move within weeks. Prompts it answers from memory move over months, and only through what others publish about you. Plan for both and measure them separately.
Frequently asked questions
What are the three doors of AI visibility?
Reach, Recognize and Believe. Reach asks whether AI engines can access your site. Recognize asks whether they identify your brand as a distinct entity. Believe asks whether independent sources support what is said about you. Each door depends on the one before it.
Should I block GPTBot?
That’s a licensing decision. GPTBot collects training data. OAI-SearchBot is what gets you into ChatGPT search answers. You can block GPTBot and keep OAI-SearchBot open.
Does an open robots.txt guarantee AI citations?
No. Access is a precondition. Whether you get named depends on the other two doors, and no one can honestly guarantee citations.
Do I need a Wikipedia article?
No. Most companies don’t meet Wikipedia’s notability bar. A referenced Wikidata item, consistent Organization schema and matching profiles come first.
Does llms.txt help?
A little, for some non-Google engines. It’s not a Google ranking factor and AI bots rarely request it today. Add a simple one if it’s cheap, but don’t make it your main project.
Is GEO different from SEO?
Good SEO is most of good GEO. Rankings get you into the pool engines read from. The three doors decide whether you get named.
Join the benchmark
This study isn’t a one-off. I keep refining the Score Card, so it’s now a benchmark. Score your own site against the same three doors in about 10 minutes, and you’ll get your weakest door and the three gaps we’d close first by email.
Want to see what the engines actually say about you? Score yourself first, then request a free AI Visibility Snapshot: real buyer questions across five engines, who gets named instead of you, and three gaps in dependency order. For the full program, see our GEO consulting service. We don’t guarantee rankings or citations. We measure, fix in order and show what moved.
Turkish readers: stradiji.com/tr/geo-skor-karti
Key terms used in this study
New to some of these terms? Each one links to a short definition in our SEO and AI search glossary. Or follow the full 12-stage GEO Roadmap.
- Generative Engine Optimization (GEO): making your brand easy for AI engines to find, understand and cite.
- AI visibility: how often your brand appears in AI-generated answers.
- Knowledge Panel: the entity box Google shows when it is confident who you are.
- Structured data: machine-readable facts about your page and organization.
- Entity optimization: making sure engines connect your name to one clear, consistent entity.
- Citation optimization: shaping content so AI answers can quote and link it.
- Zero-click search: searches that end on the results page without a visit.
Sources
- Cloudflare Developer Docs, “Block AI Bots” and AI bot policies, new defaults on Sept. 15, 2026: developers.cloudflare.com
- OpenAI, “Overview of OpenAI Crawlers”: platform.openai.com/docs/bots
- Anthropic, crawler documentation (ClaudeBot, Claude-SearchBot, Claude-User): support.claude.com
- Perplexity, “Perplexity Crawlers”: docs.perplexity.ai/guides/bots
- Google Search Central, “Google’s common crawlers” (Google-Extended): developers.google.com
- Wikidata, “Notability”: wikidata.org
- Stradiji, ChatGPT Built Its Own Search Index (Sept. 2026) and ChatGPT Decides Before It Searches (Aug. 2026)
- Stradiji, Off-Page GEO: Win Citations, Not Backlinks
Updated Oct. 12, 2026: added the key findings table and the overall “nearly nine in ten” figure; expanded the method note; added the AI bot table, a sample robots.txt and the Cloudflare Sept. 15 default change; corrected the Bing and Google-Extended guidance; added the category test, Wikidata steps, a schema example, the independent proof list, a measurement habit, a 30-minute check and an FAQ.

These May Also Interest You
The SEOs Diners Club · Weekly newsletter
Every Monday: what's actually moving in SEO and AI search
Mert Erkal breaks down one big shift each week, backed by real tests and data.
Free · 246 weekly issues since 2022 · Unsubscribe anytime
